Fast Warm Reads
L1 memory caching with optional Window TinyLFU admission. Benchmark actual throughput and memory use on your workload.
L1 RAM → L1.5 disk or /dev/shm spill → L2 Redis/Valkey. Bounded local tiers, per-process singleflight, and configurable distributed invalidation.
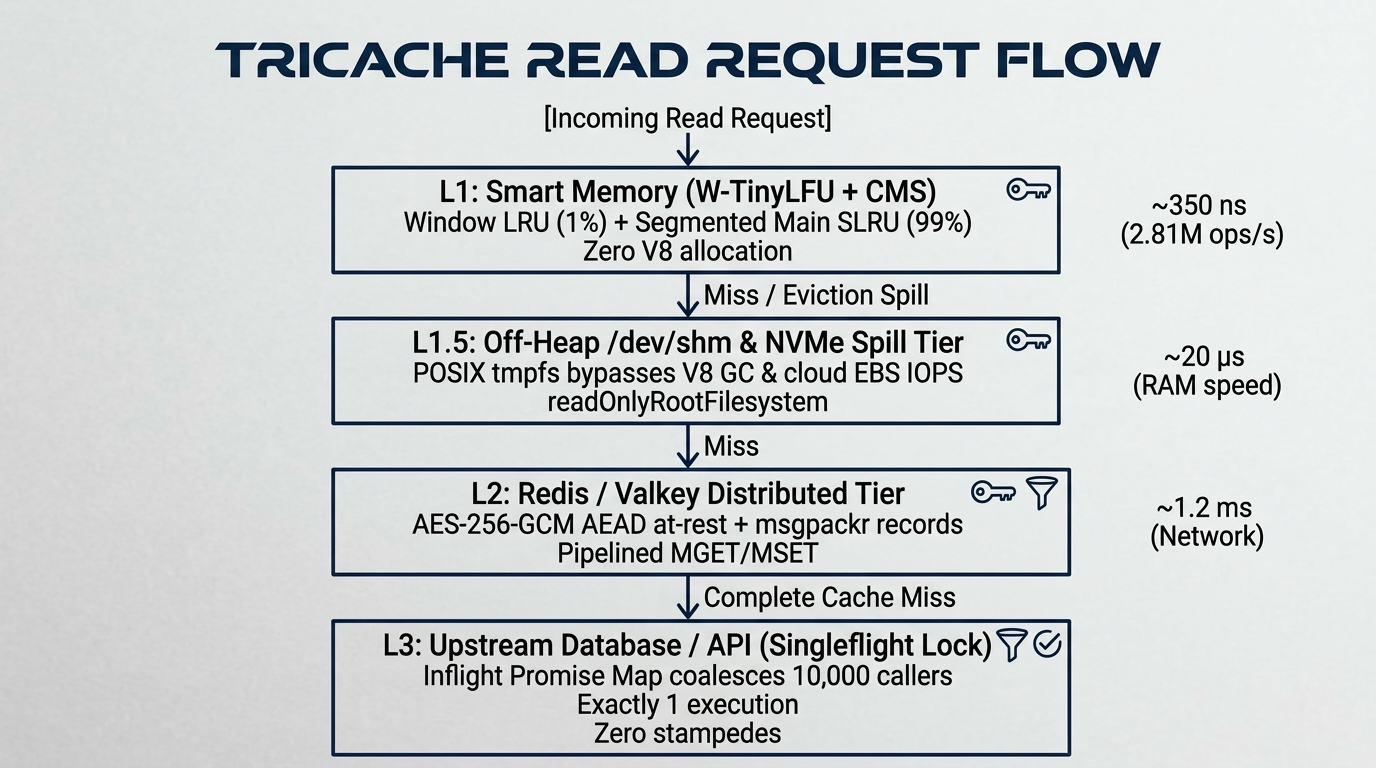
                           [Incoming Read Request]
                                      │
                                      ▼
             ┌──────────────────────────────────────────────────┐
             │       L1: Smart Memory (W-TinyLFU + CMS)         │  Bounded packed data
             │   Window LRU (1%) + Segmented Main SLRU (99%)    │  Workload-dependent latency
             └────────────────────────┬─────────────────────────┘
                                      │ Miss / Eviction Spill
                                      ▼
             ┌──────────────────────────────────────────────────┐
             │    L1.5: Off-Heap /dev/shm & NVMe Spill Tier     │  Bounded write concurrency
             │   tmpfs counts against container memory usage  │  Writable mount required
             └────────────────────────┬─────────────────────────┘
                                      │ Miss
                                      ▼
             ┌──────────────────────────────────────────────────┐
             │       L2: Redis / Valkey Distributed Tier        │  ~1.2 ms (Network)
             │   AES-256-GCM AEAD at-rest + msgpackr records    │  Pipelined MGET/MSET
             └────────────────────────┬─────────────────────────┘
                                      │ Complete Cache Miss
                                      ▼
             ┌──────────────────────────────────────────────────┐
             │   Upstream Database / API (Singleflight)         │  Per process/key
             │   Inflight Promise Map coalesces concurrent work│  Not a fleet-wide lock
└──────────────────────────────────────────────────┘First-class drivers and turnkey adapters built for zero serialization overhead across modern runtimes.